Note
Click here to download the full example code
NBLAST#
Compare neuron morphology with NBLAST — the concepts and a first run.
What is NBLAST?#
A brief introduction (modified from Jefferis lab's website):
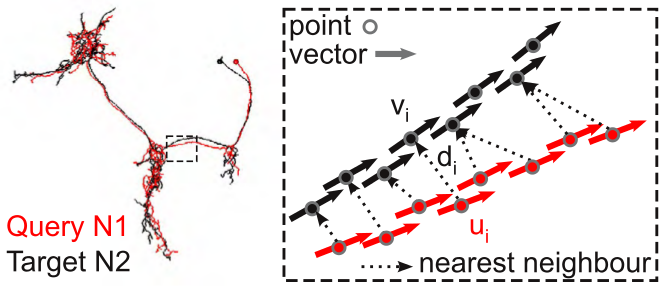
NBLAST works by decomposing neurons into point and tangent vector representations - so called "dotprops". Similarity between a given query and a given target neuron is determined by:
-
Nearest-neighbor search:
For each point + tangent vector \(u_{i}\) of the query neuron, find the closest point + tangent vector \(v_{i}\) on the target neuron (this is a simple nearest-neighbor search using Euclidean distance).
-
Calculate a raw score:
The raw score is a
weightedproduct from the distance \(d_{i}\) between the points in each pair and the absolute dot product of the two tangent vectors \(| \\vec{u_i} \cdot \\vec{v_i} |\).The absolute dot product is used because the orientation of the tangent vectors typically has no meaning in our data representation.
Where the scoring function comes from
A suitable scoring function \(f\) was determined empirically (see the NBLAST paper) and is shipped with NAVis as scoring matrices:
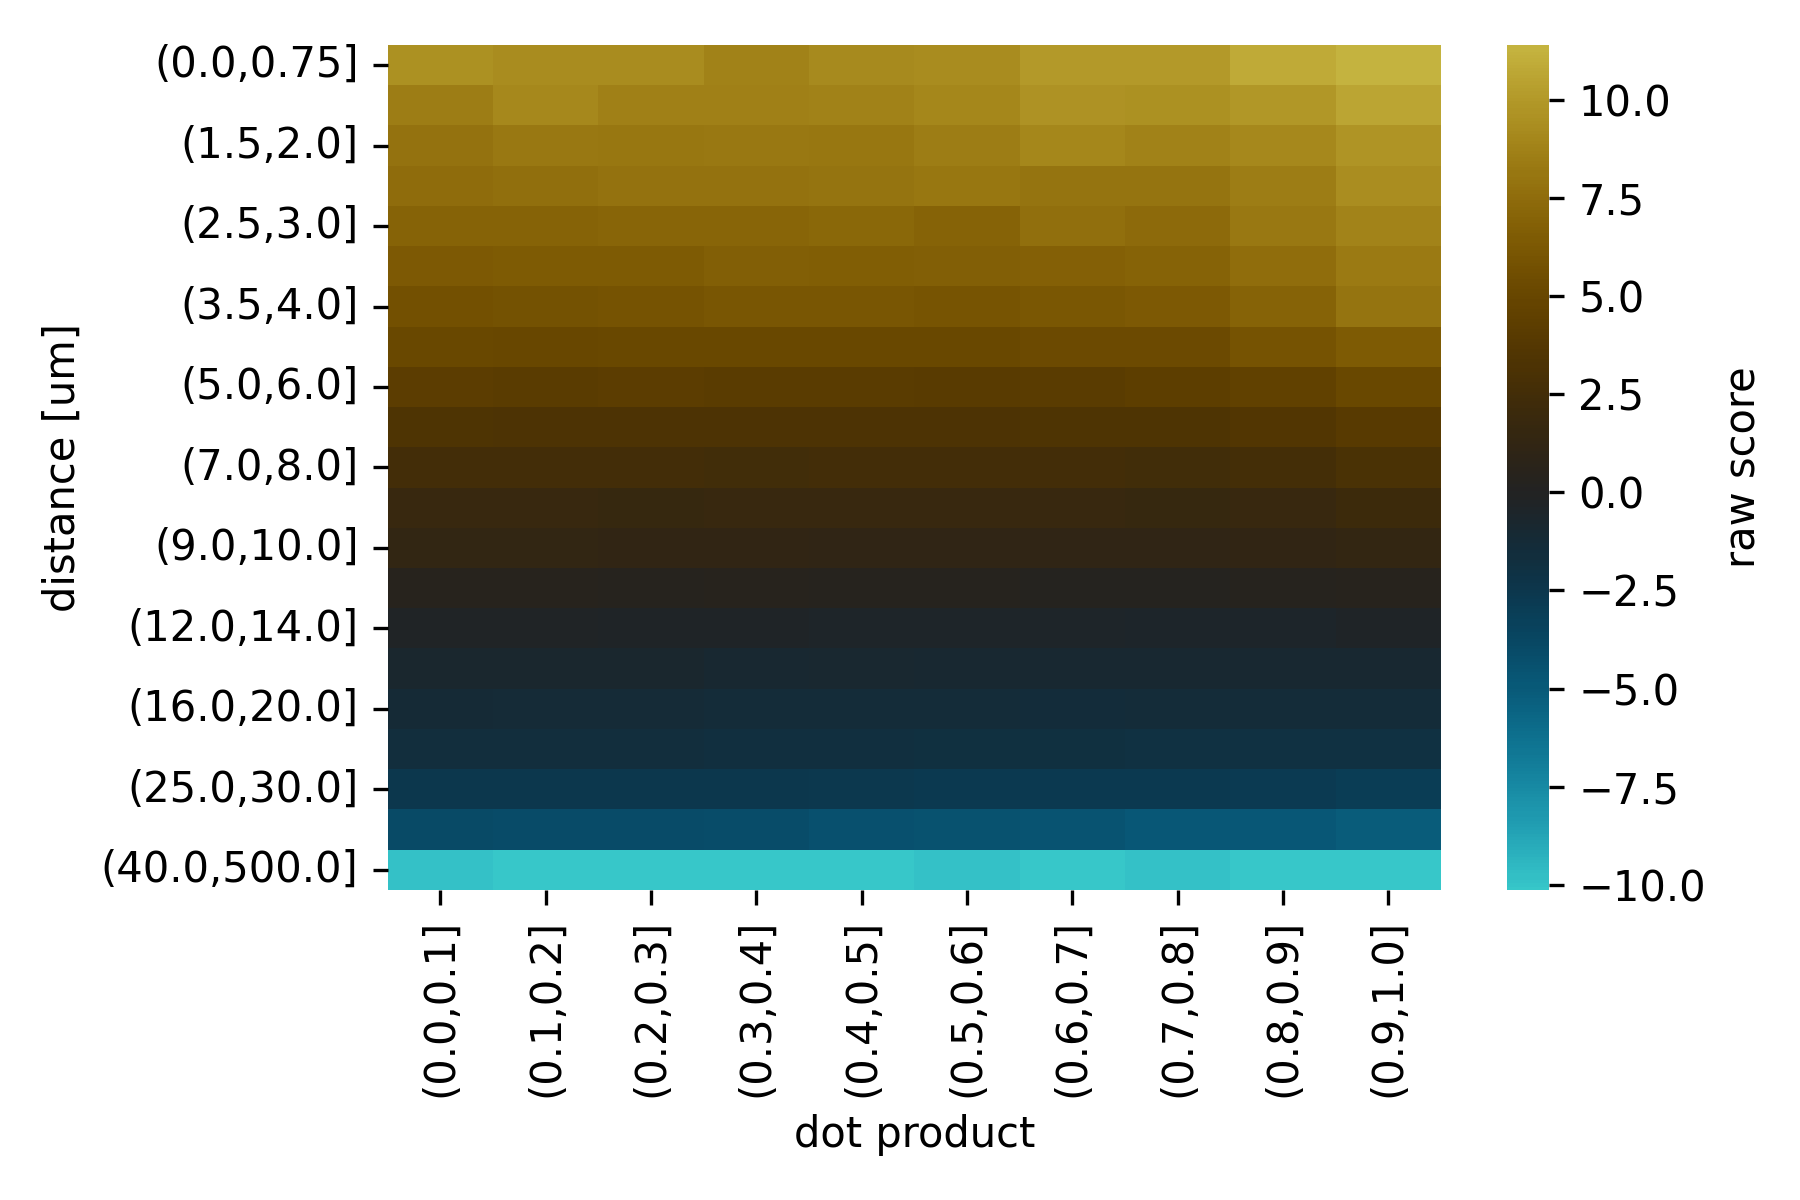
Importantly, these matrices were created using Drosophila neurons from the FlyCircuit light-level dataset which are in microns. Consequently, you should make sure your neurons are also in micrometer units for NBLAST! If you are working on non-insect neurons you might have to play around with the scaling to improve results. Alternatively, you can also produce your own scoring function (see this tutorial).
-
Produce a per-pair score:
This is done by simply summing up the raw scores over all point + tangent vector pairs for a given query-target neuron pair.
-
Normalize raw score
This step is optional but highly recommended: normalizing the raw score by dividing by the raw score of a self-self comparison of the query neuron.
Putting it all together:
graph LR
    A["Query + target"] -->|"1. nearest neighbour"| B["Point pairs"];
    B -->|"2. scoring function f"| C["Raw scores"];
    C -->|"3. sum over pairs"| D["Raw score S"];
    D -->|"4. normalise"| E["Final score"];
The formula for the raw score \(S\) is:
The direction of the comparison matters!
Consider two very different neurons - one large, one small - that overlap in space. If the small neuron is the query, you will always find a close-by nearest-neighbour among the many points of the large target neuron. Consequently, this small large comparison will produce a decent NBLAST score. By contrast, the other way around (large small) will likely produce a bad NBLAST score because many points in the large neuron are far away from the closest point in the small neuron. In practice, we typically use the mean between those forward and the reverse scores. This is done either by running two NBLASTs (query target and target query), or by passing e.g. scores="mean" to the respective NBLAST function.
navis.nblast also takes scores="both", which keeps the two directions apart instead of combining them: you get one row per query per direction, stacked under a (query, score) index, so you can decide what to do with them yourself.
Running NBLAST#
Broadly speaking, there are two applications for NBLAST:
- Matching neurons between two datasets
- Clustering neurons into morphologically similar groups
Before we get our feet wet, two things to keep in mind:
- neurons should be in microns as this is what NBLAST's scoring matrices have been optimized for (see above)
- neurons should have similar sampling resolution (i.e. points per unit of cable)
Speeding up NBLAST
Three independent knobs, cheapest first:
n_cores: every NBLAST function takes one, and it defaults to half your cores. This is the main dial.- pykdtree (
pip3 install pykdtree) gives the nearest-neighbour search a ~2x boost. - navis-fastcore reimplements NAVis' hot paths in Rust. It is a required dependency, so you already have it, and NAVis reaches for it on its own wherever it can - generating the dotprops, for one. Its NBLAST backend, though, is a separate and opt-in thing: see choosing a backend below.
If you installed NAVis with the pip install navis[all] option you already have pykdtree too.
See Scaling up at the end for what to do when one machine is not enough.
OK, let's get started!
We will use the example neurons that come with NAVis. These are all of the same type, so we don't expect to find very useful clusters - good enough to demo though!
Load example neurons
import navis

nl = navis.example_neurons()
NBLAST works on dotprops - these consist of points and tangent vectors describing the shape of a neuron and are represented by the navis.Dotprops class in NAVis. You can generate those dotprops from skeletons (i.e. Skeletons), meshes (i.e. Meshes) (see navis.make_dotprops for details) or straight from image data (see navis.read_nrrd and navis.read_tiff) - e.g. confocal stacks.
# Convert neurons into microns (they are 8nm)
nl_um = nl / (1000 / 8)

# Generate dotprops
dps = navis.make_dotprops(nl_um, k=4, resample=False)

# Run the actual NBLAST: the first two vs the last two neurons
nbl = navis.nblast(dps[:2], dps[2:], progress=False)
nbl
The nbl scores dataframe has the query neurons as rows and the target neurons as columns.
Let's run an all-by-all NBLAST next:
aba = navis.nblast_allbyall(dps, progress=False)
aba
This demonstrates two things:
- The forward and reverse scores are never exactly the same (as noted above).
- The diagonal is always 1 because it is a self-self comparison (i.e. a perfect match) and we normalize against that.
Let's run some quick & dirty analysis just to illustrate things.
For hierarchical clustering we need the matrix to be symmetrical - which our all-by-all matrix is not. We will therefore use the mean of forward and reverse scores (you could also use e.g. the minimum or the maximum):
aba_mean = (aba + aba.T) / 2
We also need distances instead of similarities!
Invert to get distances Because our scores are normalized, we know the max similarity is 1
aba_dist = 1 - aba_mean
aba_dist
Now we can use scipy's hierarchical clustering to generate a dendrogram
from scipy.spatial.distance import squareform
from scipy.cluster.hierarchy import linkage, dendrogram, set_link_color_palette

import matplotlib.pyplot as plt
import matplotlib.colors as mcl
import seaborn as sns

set_link_color_palette([mcl.to_hex(c) for c in sns.color_palette("muted", 10)])

# To generate a linkage, we have to bring the matrix from square-form to vector-form
aba_vec = squareform(aba_dist, checks=False)

# Generate linkage
Z = linkage(aba_vec, method="ward")

# Plot a dendrogram
dn = dendrogram(Z, labels=aba_mean.columns)

ax = plt.gca()
ax.set_xticklabels(ax.get_xticklabels(), rotation=30, ha="right")

sns.despine(trim=True, bottom=True)
plt.tight_layout()
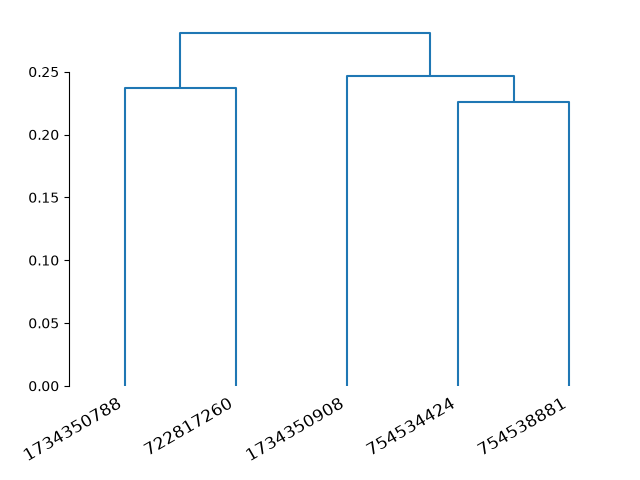
We'll leave it there for now. Here are the NBLAST functions we've seen so far, plus two for when things get big — and when to reach for each:
| Function | What it does | Use when |
|---|---|---|
navis.nblast | classic query target NBLAST | matching neurons between two datasets |
navis.nblast_allbyall | pairwise, all-by-all NBLAST | clustering neurons into morphologically similar groups |
navis.nblast_smart | a "smart" NBLAST that cuts corners | running very large NBLASTs |
navis.nblast_knn | only the top k matches per query | matching against a large reference set |
Another flavour: syNBLAST#
SyNBLAST is synapse-based NBLAST: instead of turning neurons into dotprops, we use their synapses to perform NBLAST (minus the vector component). This is generally faster because we can skip generating dotprops and calculating vector dotproducts. It also focusses the attention on the synapse-bearing axons and dendrites, effectively ignoring the backbone. This changes the question from "Do neurons look the same?" to "Do neurons have in- and output in the same area?". See navis.synblast for details.
Let's try the above but with syNBLAST:
# Importantly, we still want to use data in microns!
synbl = navis.synblast(nl_um, nl_um, by_type=True, progress=False)
synbl
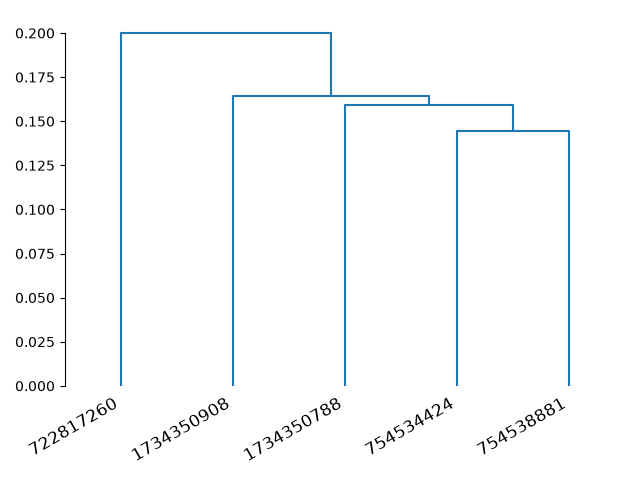
The same as above, we can run an all-by-all synNBLAST and generate a dendrogram:
aba_vec = squareform(((synbl + synbl.T) / 2 - 1) * -1, checks=False)

Z = linkage(aba_vec, method="ward")

dn = dendrogram(Z, labels=synbl.columns)

ax = plt.gca()
ax.set_xticklabels(ax.get_xticklabels(), rotation=30, ha="right")

sns.despine(trim=True, bottom=True)
plt.tight_layout()
A real-world example#
The toy data above is not really suited to demonstrate NBLAST because these neurons are of the same type (i.e. we do not expect to see differences).
Let's try something more elaborate and pull some hemibrain neurons from neuPrint.
Needs network access and a neuPrint token
This section fetches neurons live from neuPrint, so it needs an internet connection. You'll also need to install the neuprint-python package (pip3 install neuprint-python), make a neuPrint account and generate/set an authentication token. See the neuPrint documentation for details, or the dedicated NAVis neuPrint tutorial.
Once that's done we can get started by importing the neuPrint interface from NAVis:
import navis.interfaces.neuprint as neu

# Set a client
client = neu.Client("https://neuprint.janelia.org", dataset="hemibrain:v1.2.1")
Next we will fetch all olfactory projection neurons of the lateral lineage using a regex pattern.
pns = neu.fetch_skeletons(
    neu.NeuronCriteria(type=".*lPN.*", regex=True), with_synapses=True, client=client
)

# Drop neurons on the left hand side
pns = pns[[not n.name.endswith("_L") for n in pns]]

pns.head()
Out:
  0%|          | 0/1 [00:00<?, ?it/s]


  0%|          | 0/1 [00:00<?, ?it/s]


  0%|          | 0/1 [00:00<?, ?it/s]


  0%|          | 0/1 [00:00<?, ?it/s]


  0%|          | 0/1 [00:00<?, ?it/s]

100%|##########| 1/1 [00:00<00:00,  6.51it/s]
100%|##########| 1/1 [00:00<00:00,  6.50it/s]


100%|##########| 1/1 [00:00<00:00,  5.74it/s]
100%|##########| 1/1 [00:00<00:00,  5.74it/s]


100%|##########| 1/1 [00:00<00:00,  5.76it/s]
100%|##########| 1/1 [00:00<00:00,  5.76it/s]


100%|##########| 1/1 [00:00<00:00,  4.81it/s]
100%|##########| 1/1 [00:00<00:00,  4.81it/s]


  0%|          | 0/1 [00:00<?, ?it/s]


  0%|          | 0/1 [00:00<?, ?it/s]


  0%|          | 0/1 [00:00<?, ?it/s]


  0%|          | 0/1 [00:00<?, ?it/s]


100%|##########| 1/1 [00:00<00:00,  9.04it/s]
100%|##########| 1/1 [00:00<00:00,  9.03it/s]


100%|##########| 1/1 [00:00<00:00,  8.72it/s]
100%|##########| 1/1 [00:00<00:00,  8.71it/s]


  0%|          | 0/1 [00:00<?, ?it/s]


  0%|          | 0/1 [00:00<?, ?it/s]

100%|##########| 1/1 [00:00<00:00,  3.49it/s]
100%|##########| 1/1 [00:00<00:00,  3.49it/s]


100%|##########| 1/1 [00:00<00:00,  3.33it/s]
100%|##########| 1/1 [00:00<00:00,  3.33it/s]


  0%|          | 0/1 [00:00<?, ?it/s]


  0%|          | 0/1 [00:00<?, ?it/s]


100%|##########| 1/1 [00:00<00:00,  1.40it/s]
100%|##########| 1/1 [00:00<00:00,  1.40it/s]


100%|##########| 1/1 [00:00<00:00,  3.42it/s]
100%|##########| 1/1 [00:00<00:00,  3.41it/s]


100%|##########| 1/1 [00:00<00:00,  2.97it/s]
100%|##########| 1/1 [00:00<00:00,  2.97it/s]


100%|##########| 1/1 [00:00<00:00,  4.90it/s]
100%|##########| 1/1 [00:00<00:00,  4.89it/s]


100%|##########| 1/1 [00:00<00:00,  4.42it/s]
100%|##########| 1/1 [00:00<00:00,  4.41it/s]


  0%|          | 0/1 [00:00<?, ?it/s]


  0%|          | 0/1 [00:00<?, ?it/s]


  0%|          | 0/1 [00:00<?, ?it/s]


  0%|          | 0/1 [00:00<?, ?it/s]


  0%|          | 0/1 [00:00<?, ?it/s]
100%|##########| 1/1 [00:00<00:00, 13.41it/s]


100%|##########| 1/1 [00:00<00:00,  9.37it/s]
100%|##########| 1/1 [00:00<00:00,  9.36it/s]

100%|##########| 1/1 [00:00<00:00, 12.80it/s]

100%|##########| 1/1 [00:00<00:00, 10.91it/s]


  0%|          | 0/1 [00:00<?, ?it/s]


100%|##########| 1/1 [00:00<00:00,  7.74it/s]
100%|##########| 1/1 [00:00<00:00,  7.73it/s]


  0%|          | 0/1 [00:00<?, ?it/s]


  0%|          | 0/1 [00:00<?, ?it/s]


  0%|          | 0/1 [00:00<?, ?it/s]


  0%|          | 0/1 [00:00<?, ?it/s]

100%|##########| 1/1 [00:00<00:00,  7.85it/s]
100%|##########| 1/1 [00:00<00:00,  7.84it/s]

100%|##########| 1/1 [00:00<00:00, 12.21it/s]


100%|##########| 1/1 [00:00<00:00,  8.74it/s]
100%|##########| 1/1 [00:00<00:00,  8.73it/s]


100%|##########| 1/1 [00:00<00:00,  3.85it/s]
100%|##########| 1/1 [00:00<00:00,  3.85it/s]


  0%|          | 0/1 [00:00<?, ?it/s]


  0%|          | 0/1 [00:00<?, ?it/s]


  0%|          | 0/1 [00:00<?, ?it/s]


100%|##########| 1/1 [00:00<00:00,  3.36it/s]
100%|##########| 1/1 [00:00<00:00,  3.36it/s]

100%|##########| 1/1 [00:00<00:00, 11.11it/s]


  0%|          | 0/1 [00:00<?, ?it/s]


100%|##########| 1/1 [00:00<00:00,  5.72it/s]
100%|##########| 1/1 [00:00<00:00,  5.72it/s]


  0%|          | 0/1 [00:00<?, ?it/s]


100%|##########| 1/1 [00:00<00:00,  6.66it/s]
100%|##########| 1/1 [00:00<00:00,  6.66it/s]


  0%|          | 0/1 [00:00<?, ?it/s]


  0%|          | 0/1 [00:00<?, ?it/s]


  0%|          | 0/1 [00:00<?, ?it/s]

100%|##########| 1/1 [00:00<00:00,  6.01it/s]
100%|##########| 1/1 [00:00<00:00,  6.00it/s]


100%|##########| 1/1 [00:00<00:00,  6.62it/s]
100%|##########| 1/1 [00:00<00:00,  6.62it/s]


100%|##########| 1/1 [00:00<00:00,  5.68it/s]
100%|##########| 1/1 [00:00<00:00,  5.68it/s]


100%|##########| 1/1 [00:00<00:00,  7.83it/s]
100%|##########| 1/1 [00:00<00:00,  7.83it/s]


100%|##########| 1/1 [00:00<00:00,  7.68it/s]
100%|##########| 1/1 [00:00<00:00,  7.67it/s]


  0%|          | 0/1 [00:00<?, ?it/s]


  0%|          | 0/1 [00:00<?, ?it/s]
100%|##########| 1/1 [00:00<00:00, 11.18it/s]


  0%|          | 0/1 [00:00<?, ?it/s]


  0%|          | 0/1 [00:00<?, ?it/s]


  0%|          | 0/1 [00:00<?, ?it/s]


100%|##########| 1/1 [00:00<00:00,  9.16it/s]
100%|##########| 1/1 [00:00<00:00,  9.15it/s]

100%|##########| 1/1 [00:00<00:00, 10.69it/s]


100%|##########| 1/1 [00:00<00:00,  9.31it/s]
100%|##########| 1/1 [00:00<00:00,  9.30it/s]


  0%|          | 0/1 [00:00<?, ?it/s]


  0%|          | 0/1 [00:00<?, ?it/s]


  0%|          | 0/1 [00:00<?, ?it/s]


  0%|          | 0/1 [00:00<?, ?it/s]


100%|##########| 1/1 [00:00<00:00,  3.93it/s]
100%|##########| 1/1 [00:00<00:00,  3.93it/s]

100%|##########| 1/1 [00:00<00:00, 11.83it/s]


100%|##########| 1/1 [00:00<00:00,  4.78it/s]
100%|##########| 1/1 [00:00<00:00,  4.78it/s]


100%|##########| 1/1 [00:00<00:00,  7.95it/s]
100%|##########| 1/1 [00:00<00:00,  7.94it/s]


100%|##########| 1/1 [00:00<00:00,  5.91it/s]
100%|##########| 1/1 [00:00<00:00,  5.91it/s]


  0%|          | 0/1 [00:00<?, ?it/s]


  0%|          | 0/1 [00:00<?, ?it/s]


  0%|          | 0/1 [00:00<?, ?it/s]


  0%|          | 0/1 [00:00<?, ?it/s]

100%|##########| 1/1 [00:00<00:00,  9.50it/s]
100%|##########| 1/1 [00:00<00:00,  9.48it/s]


  0%|          | 0/1 [00:00<?, ?it/s]


100%|##########| 1/1 [00:00<00:00,  5.23it/s]
100%|##########| 1/1 [00:00<00:00,  5.22it/s]


100%|##########| 1/1 [00:00<00:00,  6.98it/s]
100%|##########| 1/1 [00:00<00:00,  6.98it/s]


  0%|          | 0/1 [00:00<?, ?it/s]


100%|##########| 1/1 [00:00<00:00,  5.66it/s]
100%|##########| 1/1 [00:00<00:00,  5.66it/s]


  0%|          | 0/1 [00:00<?, ?it/s]

100%|##########| 1/1 [00:00<00:00,  4.07it/s]
100%|##########| 1/1 [00:00<00:00,  4.07it/s]


  0%|          | 0/1 [00:00<?, ?it/s]


100%|##########| 1/1 [00:00<00:00,  6.12it/s]
100%|##########| 1/1 [00:00<00:00,  6.12it/s]


  0%|          | 0/1 [00:00<?, ?it/s]
100%|##########| 1/1 [00:00<00:00, 10.07it/s]


  0%|          | 0/1 [00:00<?, ?it/s]


  0%|          | 0/1 [00:00<?, ?it/s]


100%|##########| 1/1 [00:00<00:00,  4.78it/s]
100%|##########| 1/1 [00:00<00:00,  4.78it/s]

100%|##########| 1/1 [00:00<00:00, 10.15it/s]

100%|##########| 1/1 [00:00<00:00, 12.59it/s]


  0%|          | 0/1 [00:00<?, ?it/s]


  0%|          | 0/1 [00:00<?, ?it/s]


  0%|          | 0/1 [00:00<?, ?it/s]


100%|##########| 1/1 [00:00<00:00,  5.59it/s]
100%|##########| 1/1 [00:00<00:00,  5.58it/s]


  0%|          | 0/1 [00:00<?, ?it/s]


100%|##########| 1/1 [00:00<00:00,  7.52it/s]
100%|##########| 1/1 [00:00<00:00,  7.51it/s]


100%|##########| 1/1 [00:00<00:00,  6.06it/s]
100%|##########| 1/1 [00:00<00:00,  6.06it/s]


100%|##########| 1/1 [00:00<00:00,  5.13it/s]
100%|##########| 1/1 [00:00<00:00,  5.12it/s]


  0%|          | 0/1 [00:00<?, ?it/s]


  0%|          | 0/1 [00:00<?, ?it/s]


100%|##########| 1/1 [00:00<00:00,  4.51it/s]
100%|##########| 1/1 [00:00<00:00,  4.51it/s]


  0%|          | 0/1 [00:00<?, ?it/s]

100%|##########| 1/1 [00:00<00:00,  8.65it/s]
100%|##########| 1/1 [00:00<00:00,  8.64it/s]


100%|##########| 1/1 [00:00<00:00,  2.95it/s]
100%|##########| 1/1 [00:00<00:00,  2.95it/s]


100%|##########| 1/1 [00:00<00:00,  2.86it/s]
100%|##########| 1/1 [00:00<00:00,  2.86it/s]
Generate dotprops
# These neurons are in 8x8x8nm (voxel) resolution
pns_um = pns / (1000 / 8)  # convert to microns
pns_dps = navis.make_dotprops(pns_um, k=5)
pns_dps
Run an all-by-all NBLAST and synNBLAST
pns_nbl = navis.nblast_allbyall(pns_dps, progress=False)
pns_synbl = navis.synblast(pns_um, pns_um, by_type=True, progress=False)

# Generate the linear vectors
nbl_vec = squareform(((pns_nbl + pns_nbl.T) / 2 - 1) * -1, checks=False)
synbl_vec = squareform(((pns_synbl + pns_synbl.T) / 2 - 1) * -1, checks=False)

# Generate linkages
Z_nbl = linkage(nbl_vec, method="ward", optimal_ordering=True)
Z_synbl = linkage(synbl_vec, method="ward", optimal_ordering=True)

# Plot dendrograms
fig, axes = plt.subplots(1, 2, figsize=(12, 5))

dn1 = dendrogram(Z_nbl, no_labels=True, color_threshold=1, ax=axes[0])
dn2 = dendrogram(Z_synbl, no_labels=True, color_threshold=1, ax=axes[1])

axes[0].set_title("NBLAST")
axes[1].set_title("synNBLAST")

sns.despine(trim=True, bottom=True)
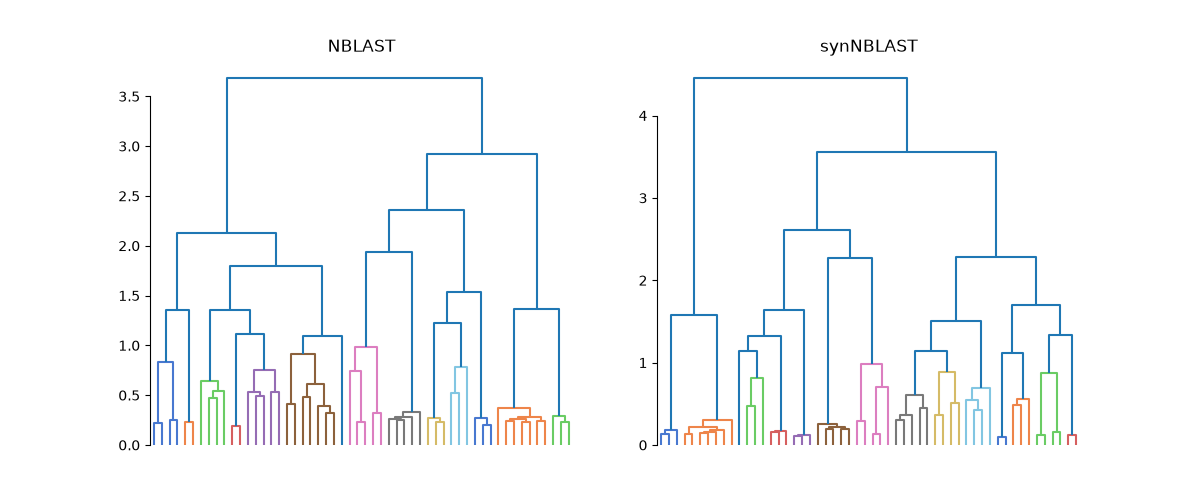
While we don't know which leaf is which, the structure in both dendrograms looks similar. If we wanted to take it further than that, we could use tanglegram to line up the two clusterings and compare them.
But let's save that for another day and instead do some plotting:
Generate clusters
from scipy.cluster.hierarchy import fcluster

cl = fcluster(Z_synbl, t=1, criterion="distance")
cl
Out:
array([ 8,  6,  6,  6, 14,  3,  8,  8,  8, 15,  2,  2,  2,  7, 13, 10, 10,
       14,  1,  1,  3, 13,  1, 10, 11, 10,  2,  2,  2,  7,  7,  7,  9,  7,
        9,  3,  4, 11,  9,  5,  9, 12,  9, 14, 15, 14, 12, 11, 11,  2, 13,
        5,  5,  8], dtype=int32)
Now plot each cluster. For simplicity we are plotting in 2D here:
import math

n_clusters = max(cl)
rows = 4
cols = math.ceil(n_clusters / 4)
fig, axes = plt.subplots(rows, cols, figsize=(20, 5 * cols))
# Flatten axes
axes = [ax for l in axes for ax in l]

# Generate colors
pal = sns.color_palette("muted", n_clusters)

for i in range(n_clusters):
    ax = axes[i]
    ax.set_title(f"cluster {i + 1}")
    # Get the neurons in this cluster
    this = pns[cl == (i + 1)]

    navis.plot2d(
        this, method="2d", ax=ax, color=pal[i], lw=1.5, view=("x", "-z"), alpha=0.5
    )

for ax in axes:
    ax.set_aspect("equal")
    ax.set_axis_off()

    # Set all axes to the same limits
    bbox = pns.bbox
    ax.set_xlim(bbox[0][0], bbox[0][1])
    ax.set_ylim(bbox[2][1], bbox[2][0])

plt.tight_layout()
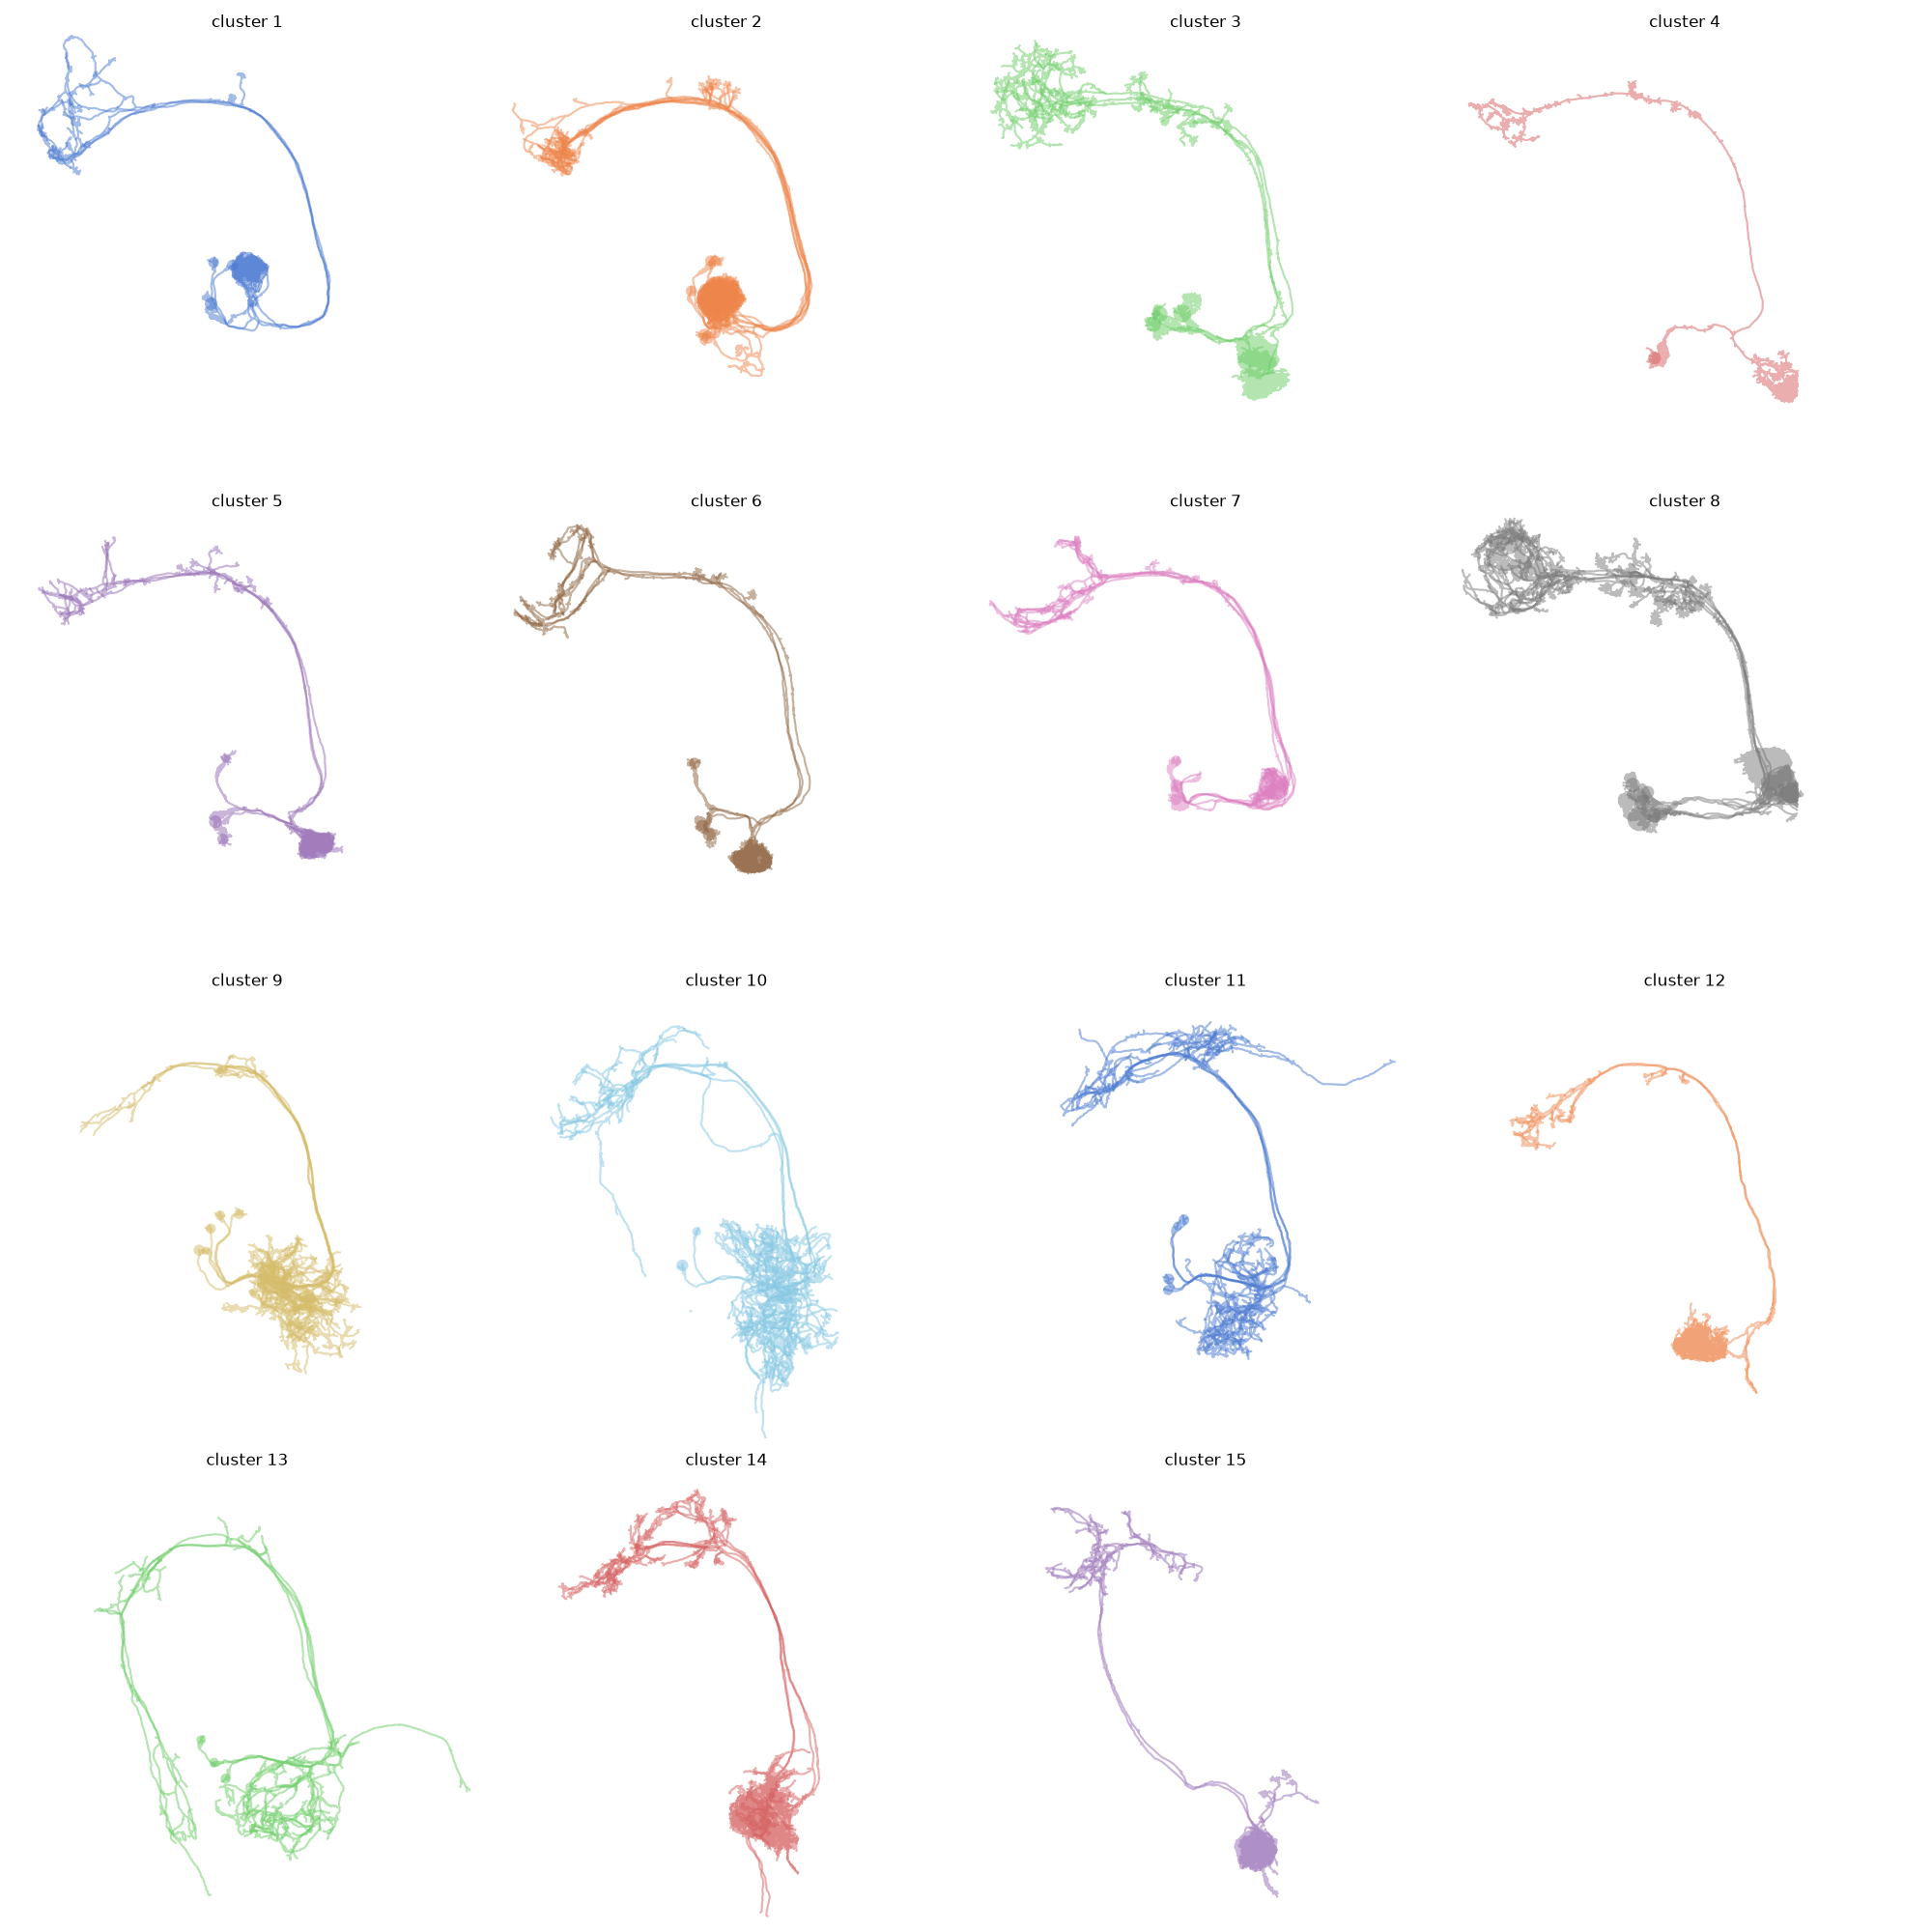
Note how clusters 3 and 8 look a bit odd? That's because these likely still contain more than one type of neuron. We should probably have gone with a slightly finer clustering. But this little demo should be enough to get you started!
Scaling up#
The examples above are small enough that none of this mattered. An NBLAST is N x M comparisons and the cost grows with the product, so at real sizes the parameters we have been ignoring start to matter.
More cores#
Every NBLAST function takes n_cores, and it defaults to half of them. NAVis cuts the query target matrix into blocks and runs those side by side:
aba = navis.nblast_allbyall(dps, n_cores=8)
You don't size the blocks yourself: NAVis times a single query and picks a grid where each block is a bounded amount of work — small enough that no core sits idle waiting for a straggler, large enough that handing one over isn't the expensive part.
Choosing a backend#
backend= selects the engine that does the scoring:
| Backend | Needs | Notes |
|---|---|---|
builtin | — | NAVis' own implementation, and the default. Supports every option, and is the only one that can spread an NBLAST across machines. |
fastcore | — | NBLAST reimplemented in Rust — considerably faster, and computes the whole matrix in one call. Doesn't support approx_nn, scores="both" or custom/analytic scoring functions. |
backend="auto" picks the fastest backend that can serve the request and falls back to builtin for anything it can't. Set it for the whole session with navis.config.default_nblast_backend = "auto", or per call:
aba = navis.nblast_allbyall(dps, backend="auto")
Don't build a matrix you're going to throw away
If all you want is the best few matches per query — the usual case when matching against a large reference set — navis.nblast_knn returns just those instead of materialising the full N x M matrix.
Another set of machines#
n_cores runs out at the size of your machine. Past that, navis.set_parallel_backend says where work runs, and the same NBLAST call runs there — the blocks of the score matrix are the units that travel:
from dask.distributed import Client

client = Client("tcp://scheduler:8786")   # or LocalCluster(), SLURMCluster(), ...

with navis.set_parallel_backend(client):
    scores = navis.nblast(query, target)
import submitit

ex = submitit.AutoExecutor(folder="logs")
ex.update_parameters(slurm_partition="cpu", timeout_min=60, mem_gb=8)

with navis.set_parallel_backend(ex):
    scores = navis.nblast(query, target)
Both need pip install navis[cluster]. How finely the matrix gets cut is read off the cluster where NAVis can see it, so n_cores on your laptop doesn't cap it.
fastcore stays on one machine
The fastcore backend computes the whole matrix in a single Rust call using its own threads, so it has nothing to hand to a parallel backend and will run everything locally. That's not the default — but it is what backend="auto" picks, so use backend="builtin" when you mean to distribute.
See the multiprocessing tutorial for the full picture on backends.
What next?#
-
Custom score matrices
Train an NBLAST scoring matrix on your own data.
-
NBLAST against FlyCircuit
Match a query neuron against the entire FlyCircuit light-level dataset.
-
Light-level vs EM
Match a confocal image stack against hemibrain EM skeletons.
Total running time of the script: ( 0 minutes 18.572 seconds)
Download Python source code: tutorial_nblast_00_intro.py